Pika H3 Flex for Text Image to Video Upscale
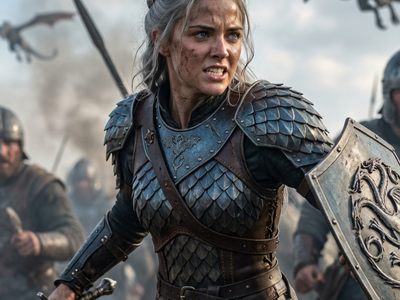
Generate a 5-second video with synced audio from a text prompt or image using Pika H3 Flex, then upscale it to 2K. Write a prompt, hit run, download.
Image to Video
Pika H3 Flex
Text to Video
Video
Video Upscale
103
ABOUT THE WORKFLOW
Generate video with synced audio, upscaled to 2K
Write a structured prompt describing a scene, its sounds, and its music. Or upload an image as a starting frame. The workflow generates a video with synced stereo audio, then upscales it to 2K in a second pass. Two videos come back: a low-res draft and the upscaled final.
Model
Pika H3 Flex by Pika Labs. A 33B open-weight video model post-trained on MiniMax H3, distilled to 6 sampling steps. Strong at audio-video sync, cinematic camera motion, and prompt following.
HOW IT WORKS
Step 1. Write your prompt
Describe the scene, soundscape, and music using the structured prompt format. Three sections: integrated_multimodal_description for the visuals, overall_soundscape for ambient and diegetic sound, non_diegetic_music for a score or soundtrack.
Works great with: cinematic scenes · product shots · atmospheric loops
Step 2. Upload an image (optional)
Add a starting frame to guide the video. The image-to-video input is turned off by default. Unmute the Image to Video nodes in the workflow to use it.
Step 3. Hit run
The model generates a low-resolution video (about 1056x608) with synced stereo audio in 6 steps. A latent upscaler then doubles the resolution to about 2K (2144x1216). Refinement LoRAs sharpen details and clean up artifacts.
Ready for: Premiere Pro · DaVinci Resolve · After Effects · any NLE
Step 4. Download your videos
Two MP4 files at 24 fps with audio. One at base resolution, one upscaled. Preview both in the workflow and download.
First time? Leave every setting as-is. The defaults are the right starting point for almost everyone.
RECOMMENDED SETTINGS
Low-Res Pass
Duration: 1–5s (default 5)
Steps: 4–8 (default 6). Don’t exceed 10.
Low-res MP: 0.3–1.0 (default 0.6 → 1056×608 at 16:9)
Aspect ratio: Default 16:9. Auto-rounds to ×32.
Seed: Default 44 fixed. Change for variety.
Upscale Pass
Upscale MP: 1.5–3.0 (default 2.5 → ~2144×1216). Above 3.0 risks OOM.
Both aspect ratios must match — mismatch = distortion.
3 upscale LoRAs stacked — don’t remove/reorder.
Upscale prompt auto-prepends “photorealistic, natural lighting, realistic textures”.
Optimization Subgraph
SigmaShift: video=12, audio=3. Don’t touch.
Attention:
comfy kitchen attentionon. Saves VRAM.LowVRAM / Chunk / Veda: All bypassed. Enable only if OOM.
Prompt
Use
integrated_multimodal_description+overall_soundscape+non_diegetic_musicformat.I2V mode: enable LoadImage + I2V prompt nodes (both bypassed by default).
Output
H264 MP4, 24fps, CRF 19.
Two outputs: draft + upscaled.
Models
Don’t swap any (UNet, CLIP, 2× VAE, Pika LoRA, 3× upscale LoRAs, latent upscaler).
LEARN
📹 Videos
ComfyUI 101 Free Course ft. Sebastian Kamph
Floyo 101 for Team Collaboration
✨ Quick links
USE CASES
🎬 Short Film and Music Video Pre-vis
Block out a shot with a text prompt, get a moving clip with a temp score and ambient sound in one pass. Review timing, framing, and mood before a live shoot.
📱 Social Media Content
Turn a product photo or concept description into a 5-second clip with music, ready to post. No separate audio editing step.
🎮 Game and VFX Previsualization
Generate environment flythroughs, character action clips, or VFX reference footage from a text description. Use the 2K upscale for client-facing presentations.
🎵 Audio-Synced Demos and Prototypes
Test how a scene feels with specific sound design and music before committing to licensed tracks or a composer. Iterate on the audio cues in the prompt and re-run.
WHAT WORKS BEST / WHAT TO AVOID
✅ Works great
Detailed structured prompts with specific visual, sound, and music cues
Single-environment scenes with clear subject and action
Cinematic camera moves described with timing (“at three seconds, the camera tilts up”)
Well-lit, clean source images when using image-to-video mode
⚠️ May produce softer results
Vague or single-line prompts with no sound or music section
Rapid scene changes or cuts within one 5-second clip
Multiple characters with complex simultaneous actions
Very long durations beyond 5 seconds (stability can drop)
FAQ
What is Pika H3 Flex?
Pika H3 Flex is an open-weight video model from Pika Labs, released October 29, 2026. It is post-trained on MiniMax H3 (33B parameters) and distilled down to 6 sampling steps. It generates video with synchronized stereo audio from text prompts, images, or multimodal references.
How does the structured prompt format work?
The prompt uses three sections. integrated_multimodal_description describes the visual scene and camera movement. overall_soundscape describes ambient and environmental sounds. non_diegetic_music describes the musical score. The model reads all three together to generate video and audio in sync. Leaving out the audio sections still produces a video, but the sound will be less intentional.
What resolution does the output reach after upscaling?
The first pass generates at about 1056x608 (0.6 megapixels at 16:9). The latent upscaler and refinement LoRAs then bring the output to about 2144x1216, which is close to 2K. Both versions are saved as MP4 files at 24 fps with audio.
Can I use Pika H3 Flex for commercial projects?
Pika H3 Flex uses open weights released under the MiniMax H3 Community License. Review the license terms on the Hugging Face model card before using outputs in commercial work. The license includes restrictions that may affect your use case.
What is the difference between Pika H3 Flex and MiniMax H3?
MiniMax H3 is the base model, a 33B dense omni-modal transformer. Pika H3 Flex is a pair of LoRA adapters that Pika trained on top of it. The main difference: Pika distilled the sampling schedule from 50 steps down to 6, so generation is faster. Pika reports it runs up to 1.8x faster than H3 Max while maintaining or improving quality across video and audio metrics.
Why does the workflow output two videos?
The first video is the low-resolution draft from the initial generation pass. The second is the upscaled version after the latent upscaler and refinement LoRAs. Having both lets you preview the draft quickly and compare it against the final. If the draft looks wrong, adjust the prompt and re-run without waiting for the full upscale pass.
How to run Pika H3 Flex online?
You can run Pika H3 Flex online through Floyo. No installation, no setup, no API key to wire up. Open the workflow in your browser, write your prompt, and hit run. Free to try.
WHY FLOYO?
Floyo is the only platform with team collaboration for ComfyUI in the browser. You run workflows with no install. You share run history, assets, and models across your team. You pay only when you generate. Floyo supports open-source and closed-source models.
A designer runs an edit and likes the result. A teammate opens that exact run from shared history and keeps going. No file handoffs. No version confusion.
For studios and enterprise teams, Floyo adds private workspaces, pooled resources, and a team usage dashboard. Other ComfyUI cloud tools run for one person at a time. Floyo runs for the whole team, with transparent per-generation costs.
Ready to try it?
Write a scene, describe the sounds, and run it. The model and upscaler are already loaded.
Questions? Watch the free course or check the FAQ above.
Read more